Pick one image generator for tens of thousands of pages and you pay in money, months, or quality. The fix is to stop choosing.
Table of Contents
Vector vs diffusion: two engines that fail in opposite places
Everything follows from how each engine makes a picture. A diffusion model denoises a raster into existence from a text prompt; you steer a probability cloud with words and accept what comes back. Vector authoring is the opposite: Claude Code writes SVG, placing every shape, color, and glow on purpose, as code.
That single difference sets their opposite strengths. Diffusion owns texture, light, and material realism. Vector owns precision, repeatability, and cost. Neither is “better.” They are a camera and a draftsman, and they fail where the other is strong.
A diffusion model is a camera; code-drawn vector is a draftsman — and a large course catalog needs both.
Where diffusion wins: real, photographable things
When the subject is tangible — food, a place, an instrument — photorealism reads as honest, and no vector engine can fake it. A cooking course is the clear case. The prompt names the scene, then spends its tail forbidding the model’s known failure modes:
Editorial still-life photograph of high-heat stir-frying: a seasoned wok mid-toss over a
blue flame, fresh vegetables and a lick of flame at the edge, prep bowls beside it on a
dark surface, a wisp of steam. Warm vivid palette, shallow depth of field, cinematic food
photography. 16:9 widescreen, high resolution. No text, letters, numbers, logos,
watermarks, faces, or hands anywhere.Code language: CSS (css)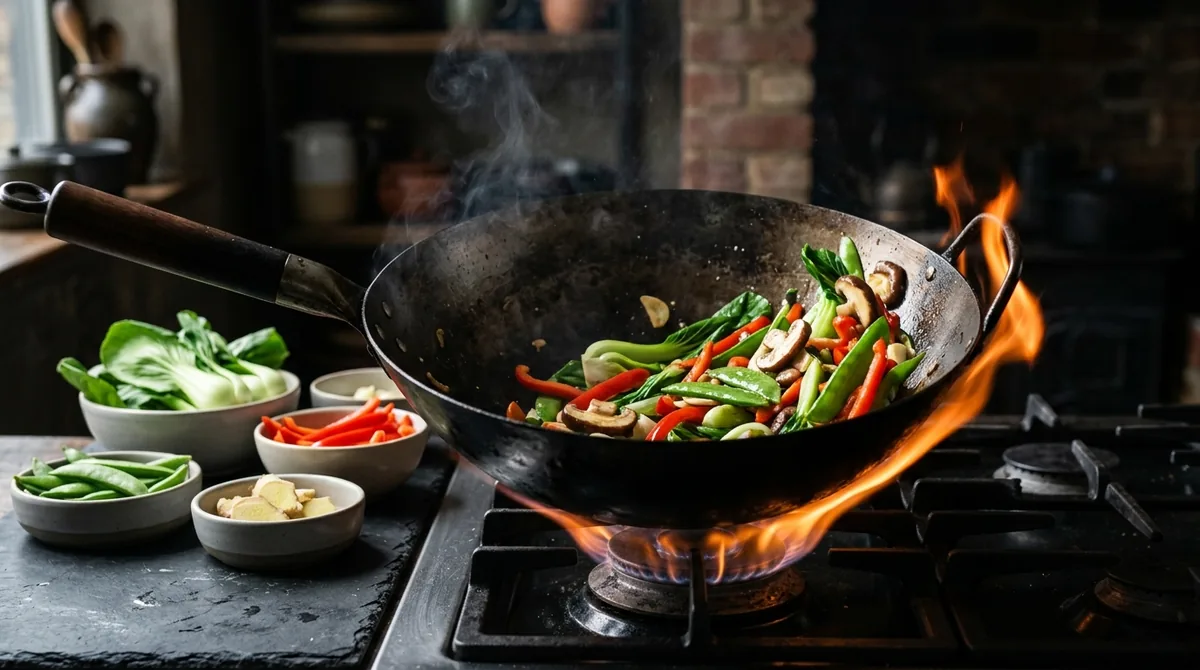
The result is appetizing and correct — and it needed a human to confirm no stray hand or invented label slipped in. In the same batch, a near-identical prompt for a different course produced a visible hand despite the ban. Diffusion approximates; it does not obey.
Where vector wins: concepts and hard science
Most of a technical catalog is not a scene — it is an idea. Software, security, data, physics, chemistry, and math are concepts, and concepts are exactly what platforms like Brilliant and edX already draw as flat illustration. Here Claude Code authors the image directly as SVG. A software-architecture course becomes a stack of clean, glowing layers, with small modules lifting off the top:
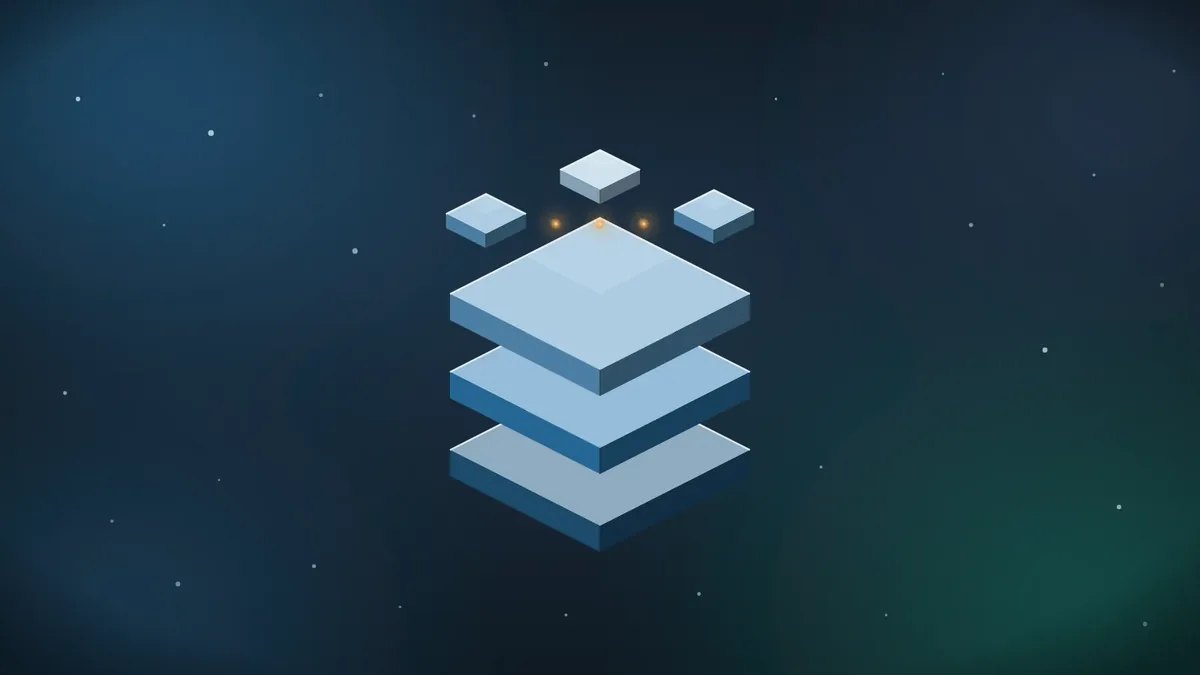
There is no garbled text and no rogue hand in this image for a structural reason: no one drew them. The file is tiny, renders sharp at any size, costs nothing to generate, and can be recolored for a new subject by editing a handful of gradient stops. Reuse the same background treatment and twenty such images read as one product.
The failure modes of diffusion are simply unavailable to a drawing you author by hand.
The quota wall changes the math
The deciding practical fact is metering. On the Google Gemini AI Pro subscription tier, the diffusion backend limits requests per rolling window — roughly ten to twelve images every five hours — and one 16:9 request costs the same whether the output is small or large. Shrinking the image saves nothing.
That ceiling is the whole reason to route well. At about fifty images a day, a bespoke photograph for every course in a 20,000-course catalog is a six-to-eight-month job. Move the conceptual half to the free vector track and the metered budget covers only the subjects that truly need a photograph.
The quota meters requests, not pixels, so a smaller image buys you nothing.
How to route a subject to the right engine
The rule is short. Ask what the subject is, then send it to the engine built for it:
- Real, textured, photographable thing (food, place, material, instrument) → diffusion.
- Concept, system, or hard-science abstraction → vector.
- Ambiguous → default to vector; it is free, instant, consistent, and rule-safe, and you can regenerate the few that truly need a photograph.
And some subjects need no generation at all – a suitable licensed stock photo may already exist; see where to find and create website images.
One more rule sits above both: review every generated image before it ships. The vector track is safe by construction, but the diffusion track will occasionally break a rule no matter how the prompt is written. For the full prompting method behind the diffusion side, see the companion guide on AI image generation best practices.
The short version
Vector vs diffusion image generation is a routing choice, not a winner. Diffusion draws the photographs vector cannot, at the cost of quota, drift, and the odd broken rule. Vector draws concepts for free, forever consistent, and never garbles text or hands. Match the engine to the subject — photographs to diffusion, ideas to vector — review every diffusion output, and the pair covers a whole catalog in a fraction of the time and cost of either engine used alone.
Frequently Asked Questions
When should I use a diffusion model instead of vector graphics?
Use diffusion when the subject is a real, photographable thing — food, a room, a landscape, an instrument — where texture and light carry the meaning. Forcing a hand-drawn vector to imitate a photograph produces a diagram of the thing, not the thing.
Can vector graphics replace AI image generation entirely?
No. Vector art is ideal for concepts, systems, and abstract science, but it cannot render believable photographic texture. A catalog that spans cooking and quantum mechanics needs both a photographic engine and a vector one.
Does generating a smaller image save quota?
Usually not. Most services count requests within a time window, not pixels, so reducing resolution does not stretch a fixed request limit. Plan a batch by the number of images you need, not their dimensions.
Why do vector images stay consistent across a set?
Because you reuse the same source code. When every image inherits one background-and-glow treatment, the set reads as a single family. A diffusion batch drifts image to image because each render is an independent draw.
How do I stop AI images from showing garbled text or extra hands?
On the vector track, never draw them — suggest form instead of spelling words. On the diffusion track, forbid them in every prompt and still review each output, because the ban is a request the model can ignore.

